General Compute’s AI Inference Valuation Surge
– 4 min read
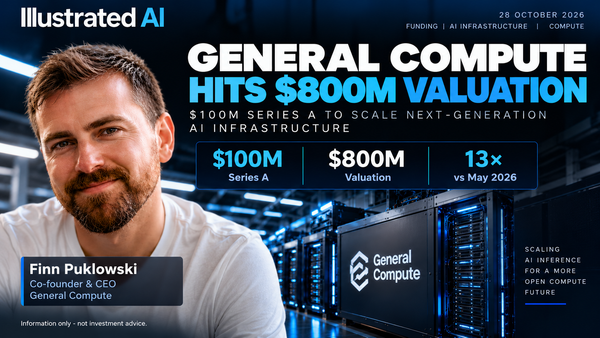
General Compute announced a $100 million Series A on 27 October 2026, co-led by Blackbird and Abstract, with Fuse Venture Partners, Village Global and others participating. The company finances, deploys and operates GPUs and specialised inference chips, offering dedicated hardware access or service-level commitments measured in tokens per second.
Invest in top private AI companies before IPO, via a Swiss platform:
 SmartProfit Finder AG
TechCrunch reported an $800 million post-money valuation, compared with $60 million after May’s seed round—approximately a 13.3-fold increase.
The investment thesis centres on recurring demand for inference as deployed models serve applications. Training, retraining and post-training also require substantial computing resources. The relative commercial importance of these workloads will depend on adoption, model development and computing efficiency.
The funding round also signals a broader thesis: specialized infrastructure that simplifies complexity for customers may be rewarded as heavily as raw scale. When computing architecture changes, markets can reprice the future quickly.
The AI race is shifting from building the biggest model to making AI respond quickly, cheaply, and reliably. Inference is where AI earns its keep — every question answered, every task completed runs on it.
As software becomes more agentic, a single user request can trigger chains of inference events, multiplying infrastructure demands dramatically. This creates a new competitive field where winning means delivering the best cost per output, fastest response, or lowest energy profile — not just raw power.
Lower inference costs expand what products can economically exist. Many AI tools look impressive in demos but fail when millions of users arrive and every interaction carries real cost. Inference infrastructure determines whether an AI product survives that transition from novelty to utility.
AI workloads have different shapes, speeds, and memory requirements. A chip excelling at one job may be inefficient at another — opening the door to specialization. Specialized chips target specific tasks: faster inference, lower power consumption, better cost per output.
General Compute describes production workloads on SambaNova hardware and a broader architecture combining GPUs with specialised accelerators. Its October announcement schedules its first major deployments for the first quarter of 2027, with more than 50 megawatts in the pipeline. Planned capacity should not be counted as commissioned infrastructure or demonstrated multi-architecture performance at scale.
Risks are real. Performance claims depend on workload type and deployment details. AI hardware evolves rapidly, and today's leading-edge chip faces tomorrow's competition. But if specialized infrastructure delivers genuinely better inference economics, value could shift from uniformity toward intelligent orchestration.
General Compute aims to spare customers from procuring and operating the underlying hardware. Customers can obtain dedicated bare-metal capacity or a tokens-per-second service-level agreement. Integration, model compatibility, monitoring and responsibility for application performance still depend on the service and contract.
Integration into customer workflows could create switching costs, but durable retention will depend on pricing, reliability, portability and available alternatives. Repeat spending and renewals would provide stronger evidence than integration alone.
However, this is capital-intensive. Expansion can require hardware expenditure before service revenue is earned, although customer commitments, prepayments and financing terms affect the funding requirement. Utilization must stay high because idle machines are expensive. Contracts signal demand but are not collected revenue — payment depends on delivery, usage, and terms. Concentration risk matters if income depends on few customers.
If executed well, the provider occupies a valuable middle layer — not owning the end application or inventing every chip, but making the ecosystem function efficiently for everyone.
Four evidence points matter most. First, deployment: planned capacity must become live capacity on schedule. Second, utilization: systems must do enough paid work to justify fixed costs. Third, unit economics: specialized chips must deliver better inference economics in real customer environments, not just benchmarks. Fourth, cash collection: contracted commitments must translate into customer payments, with attention to payment schedules, creditworthiness and concentration.
Competition from hyperscale cloud providers is a genuine threat. Financing risk is real if demand arrives slowly. Obsolescence risk is significant given AI hardware's pace of change — adaptability may matter more than any specific asset.
The broader opportunity remains compelling. AI compute is becoming heterogeneous, creating room for specialized operators. The market need likely exists. The question is which companies can turn technical complexity into a repeatable, profitable service.
The bottom line: General Compute’s financing supports an inference-infrastructure strategy combining GPUs and specialised accelerators. Existing workloads and planned deployments represent different stages of execution. The disclosures do not establish superior total costs or sustainable profitability. Investors should watch commissioned capacity, workload-specific performance, service reliability, customer concentration, collections and returns after hardware, power and financing costs.